γ-Art
Zero-Shot Sim-to-Real Articulated Object Manipulation via Large-Scale Synthetic Pretraining

Zero-Shot Sim-to-Real Articulated Object Manipulation via Large-Scale Synthetic Pretraining
01 Overview
Articulated-object manipulation demands precise contact with functional parts while satisfying joint constraints, making high-quality real-world demonstrations difficult to collect at scale. γ-Art addresses this bottleneck with γ-Sim, an articulation-aware IsaacLab-based simulation platform for asset annotation, skill and motion generation, and efficient demonstration collection. On top of it, agentic task generation creates articulated-object tasks with varied complexity and temporal horizons, while a distributed synthesis system—shown in the accompanying videos as γ-Hive—scales trajectory generation and dataset production across parallel workers. Together, these components produce γ-Art-Data, with 1,004,584 demonstrations spanning 44 task types, 5 robot setups, and 2,507 articulated objects. A VLA model pretrained on this synthetic data shows competitive simulation performance and transfers zero-shot to real-world articulated-object manipulation, demonstrating the value of scalable synthetic supervision for contact-rich tasks.
02 Platform
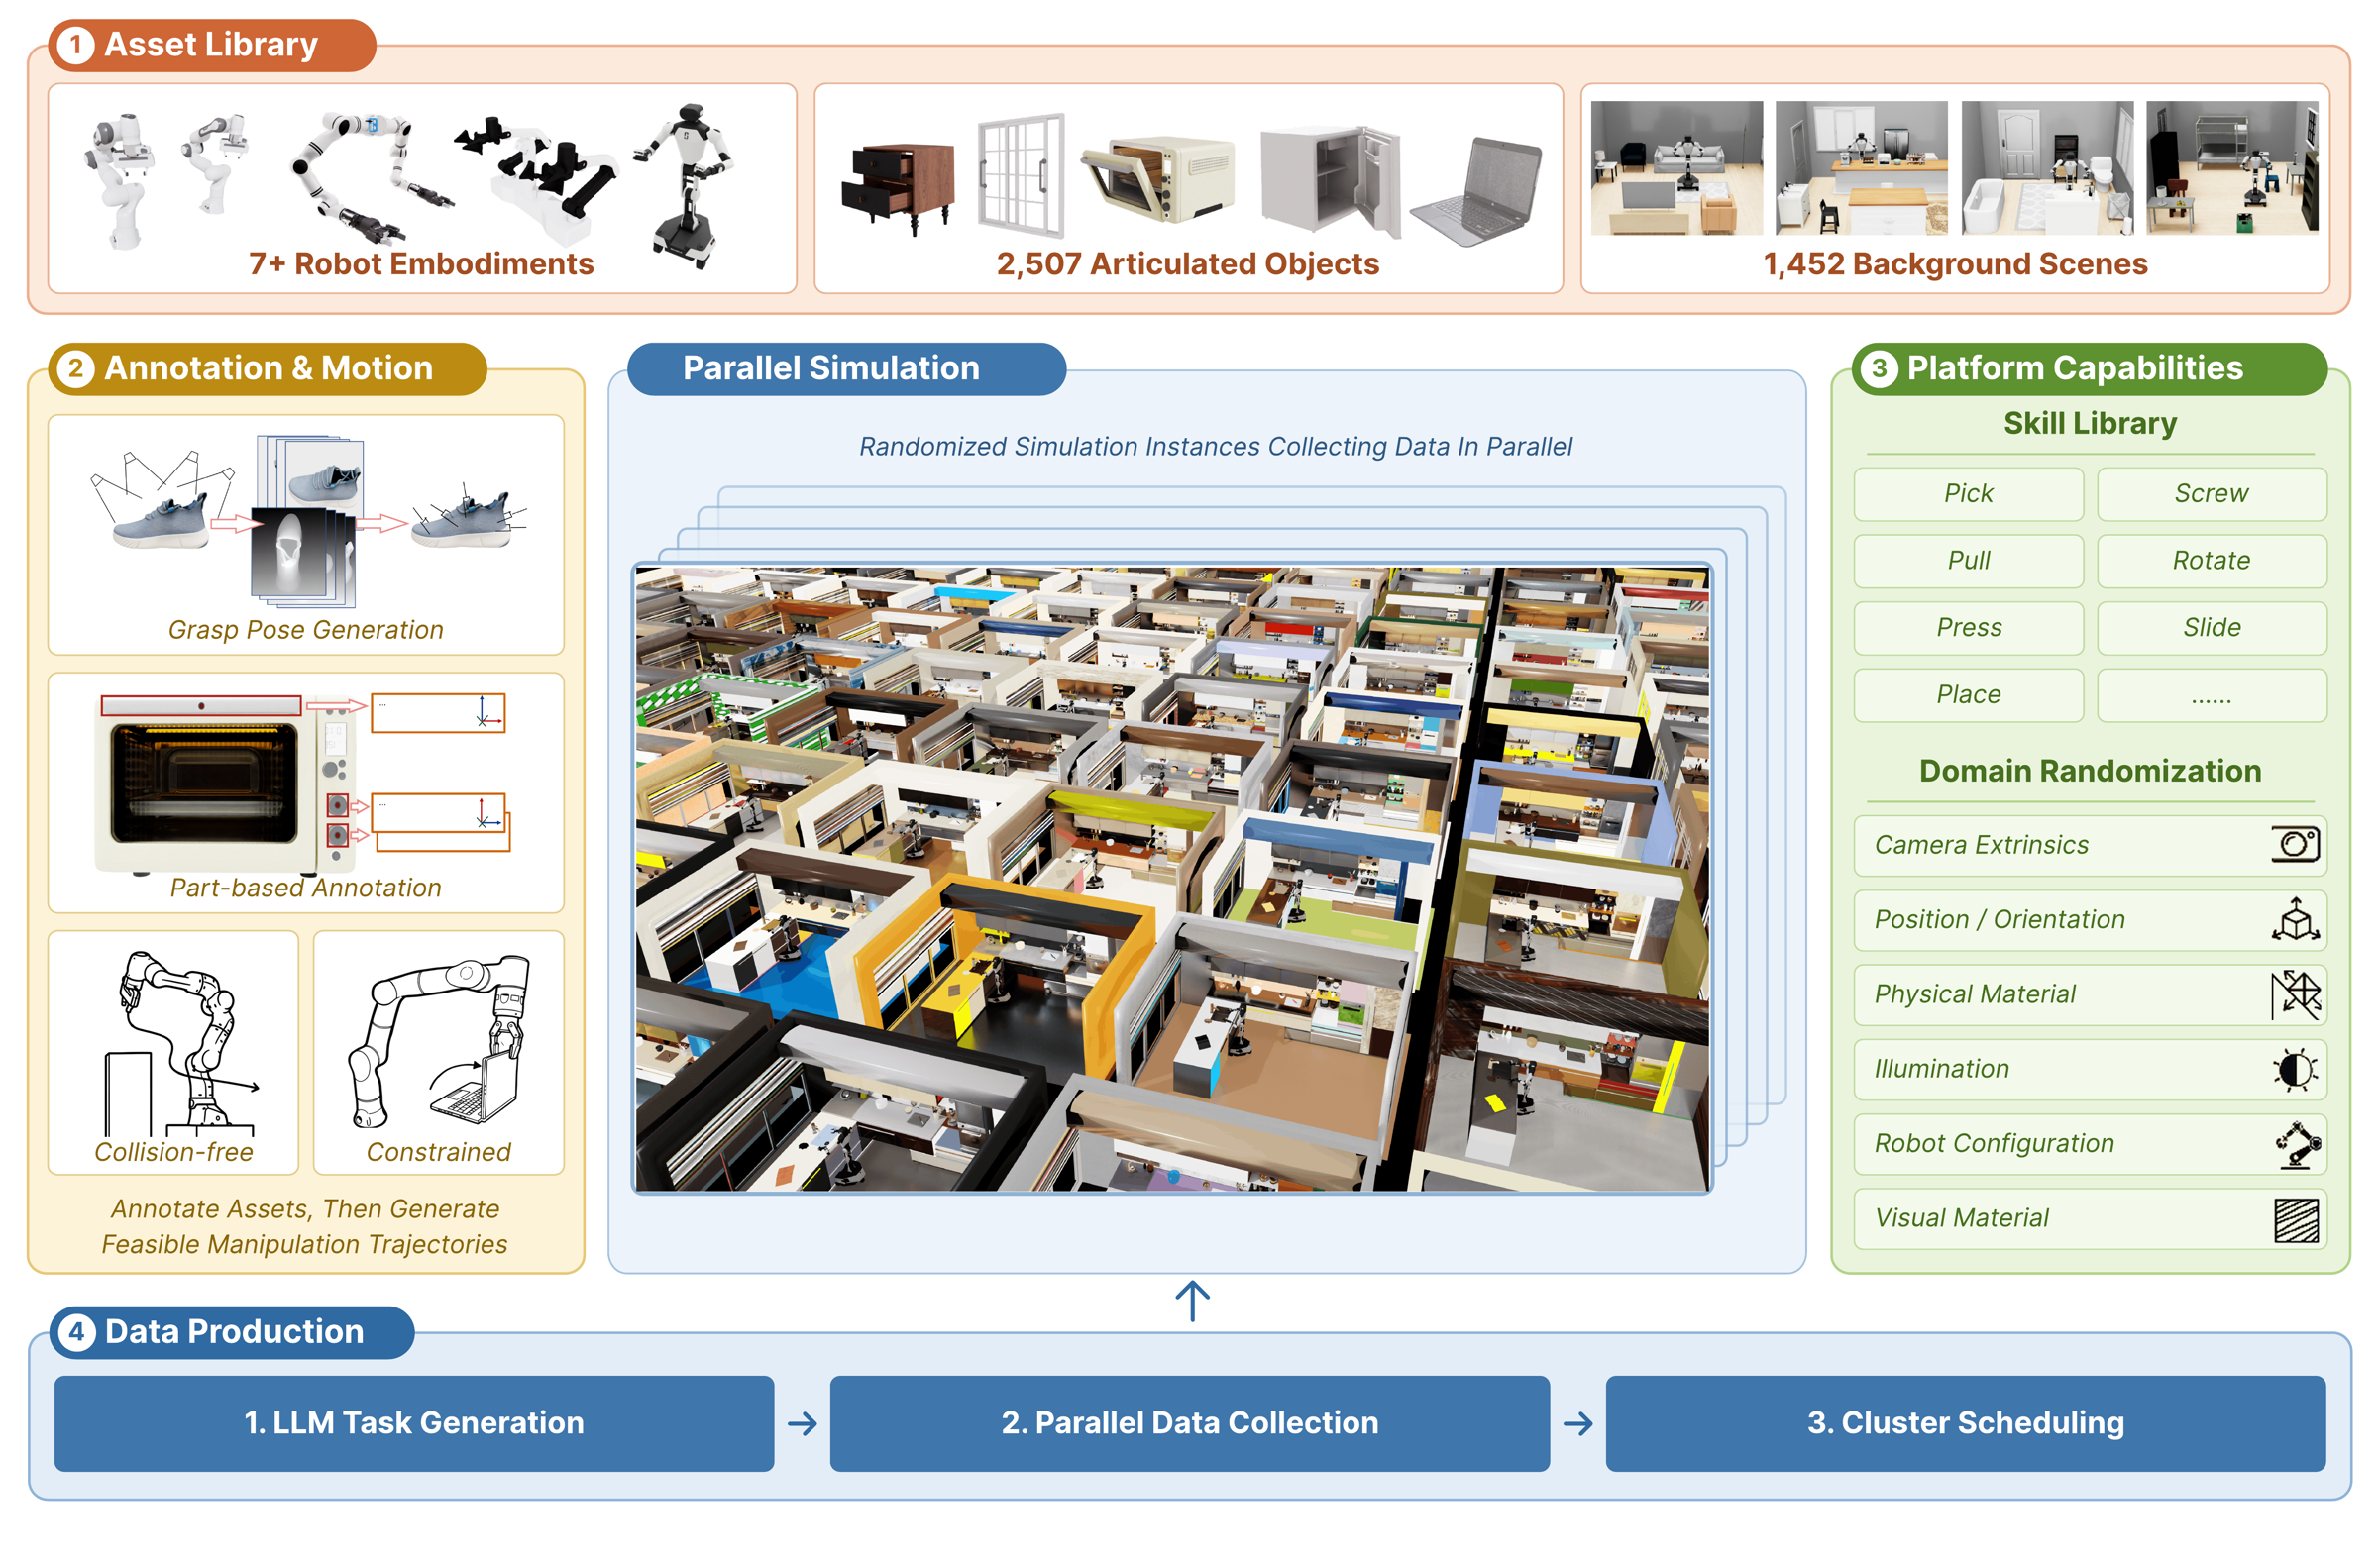
γ-Sim is a versatile IsaacLab-based simulation platform designed for articulated-object manipulation. It turns natural-language task descriptions into executable configurations and combines asset management, motion generation, parallel simulation, domain randomization, and data production into one platform.
The platform supports seven embodiments—Franka Emika Panda, RM75, AC1, R1Pro, Flexiv Rizon 4S, Marvin M6s, and Unitree H1-2—and assembles them with configurable camera layouts. Five representative setups are used in γ-Art-Data.
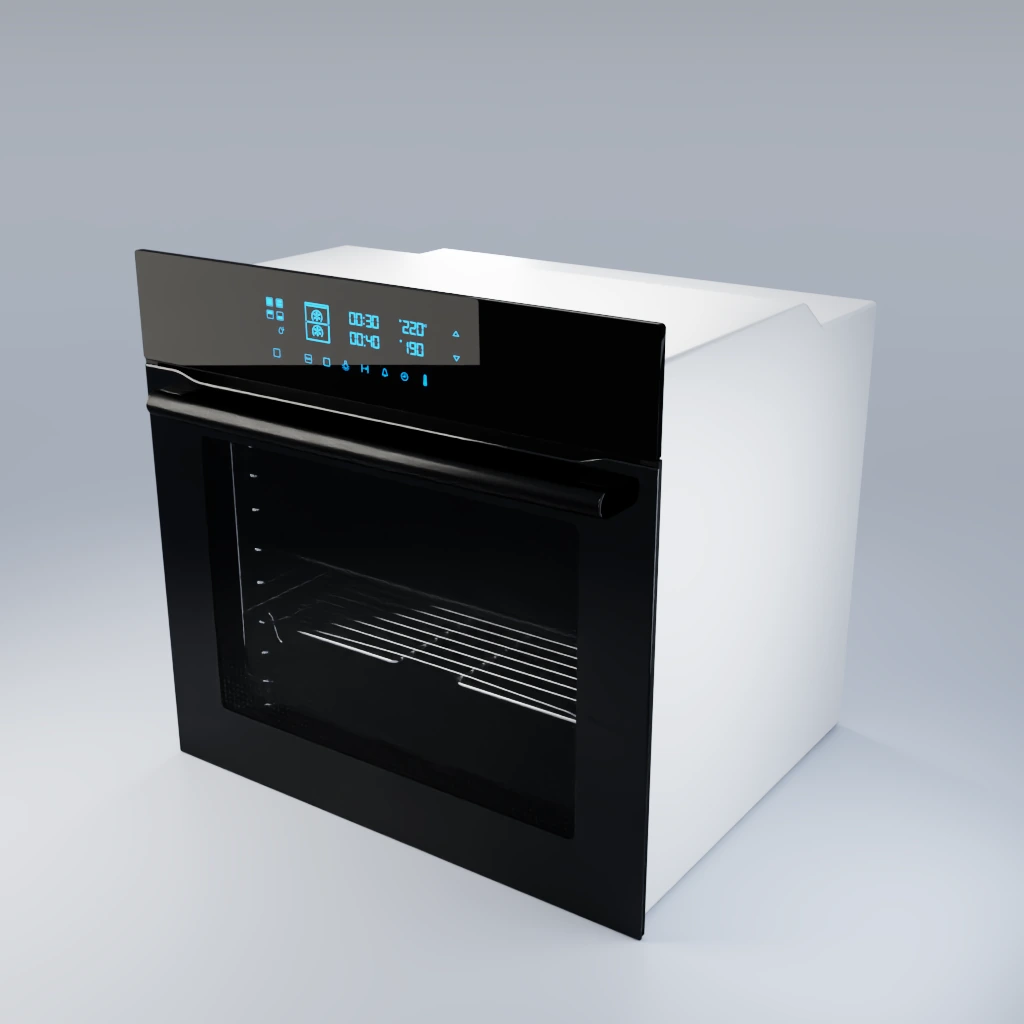
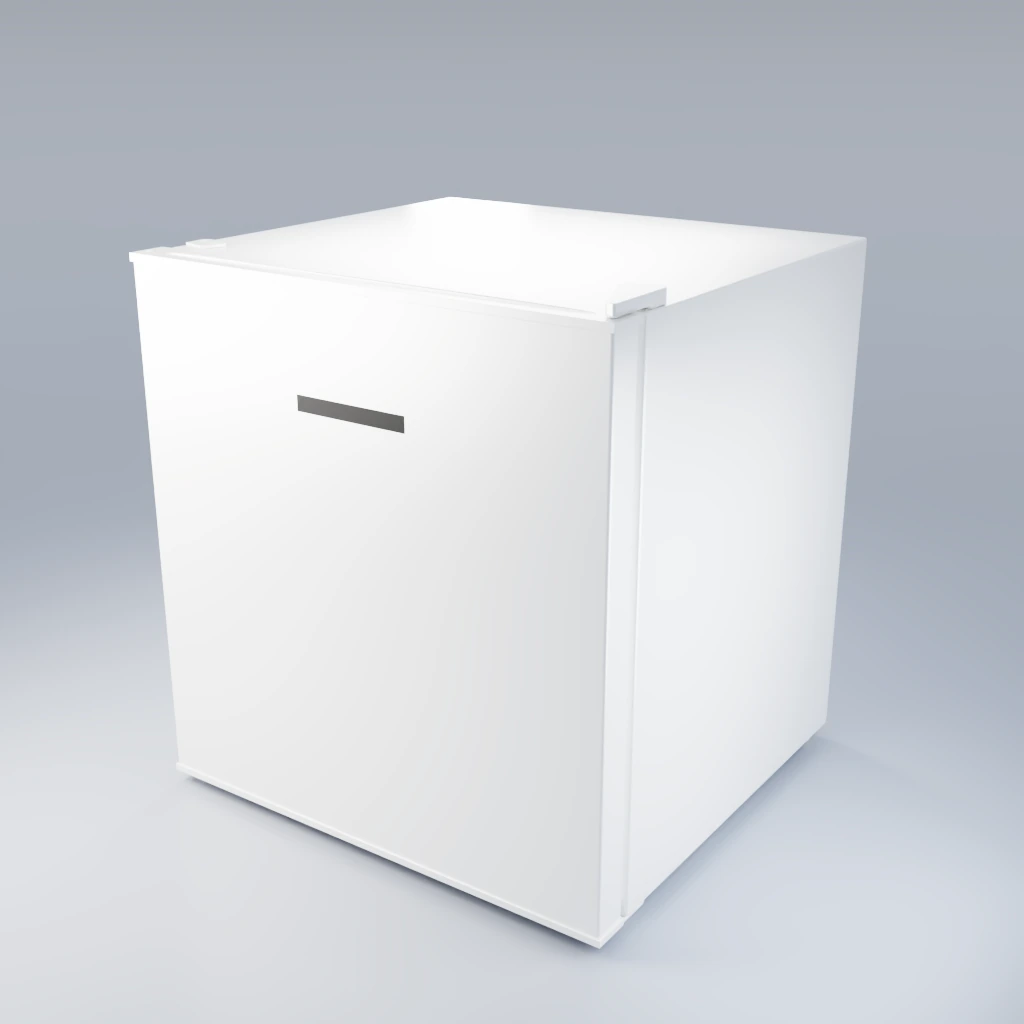
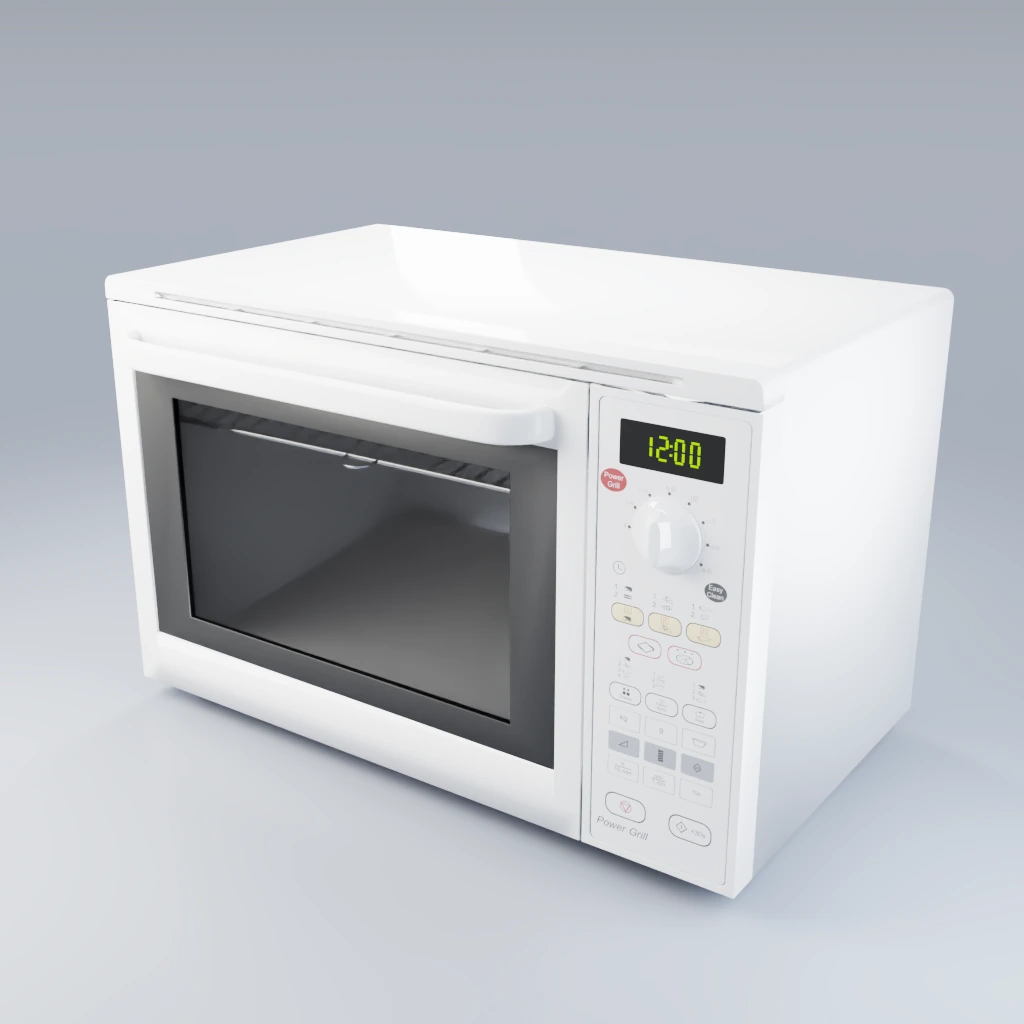
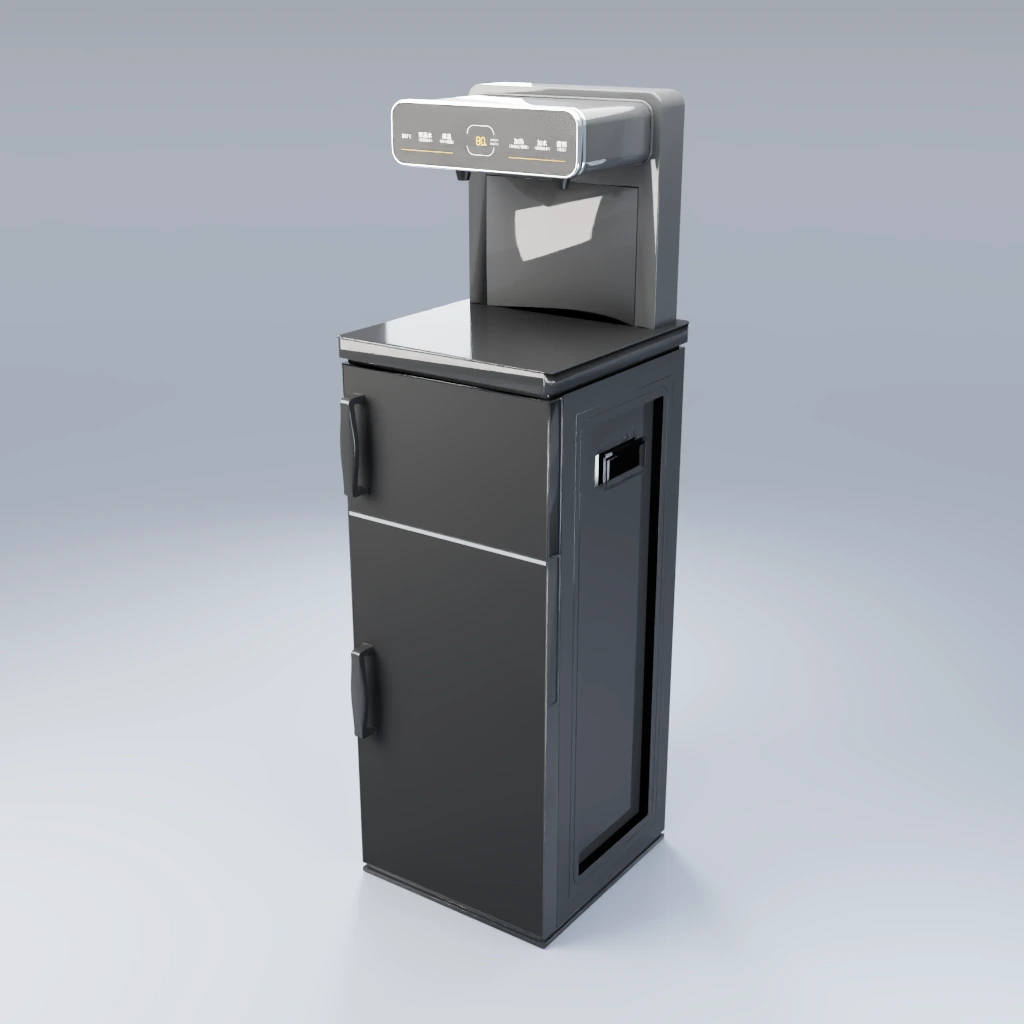
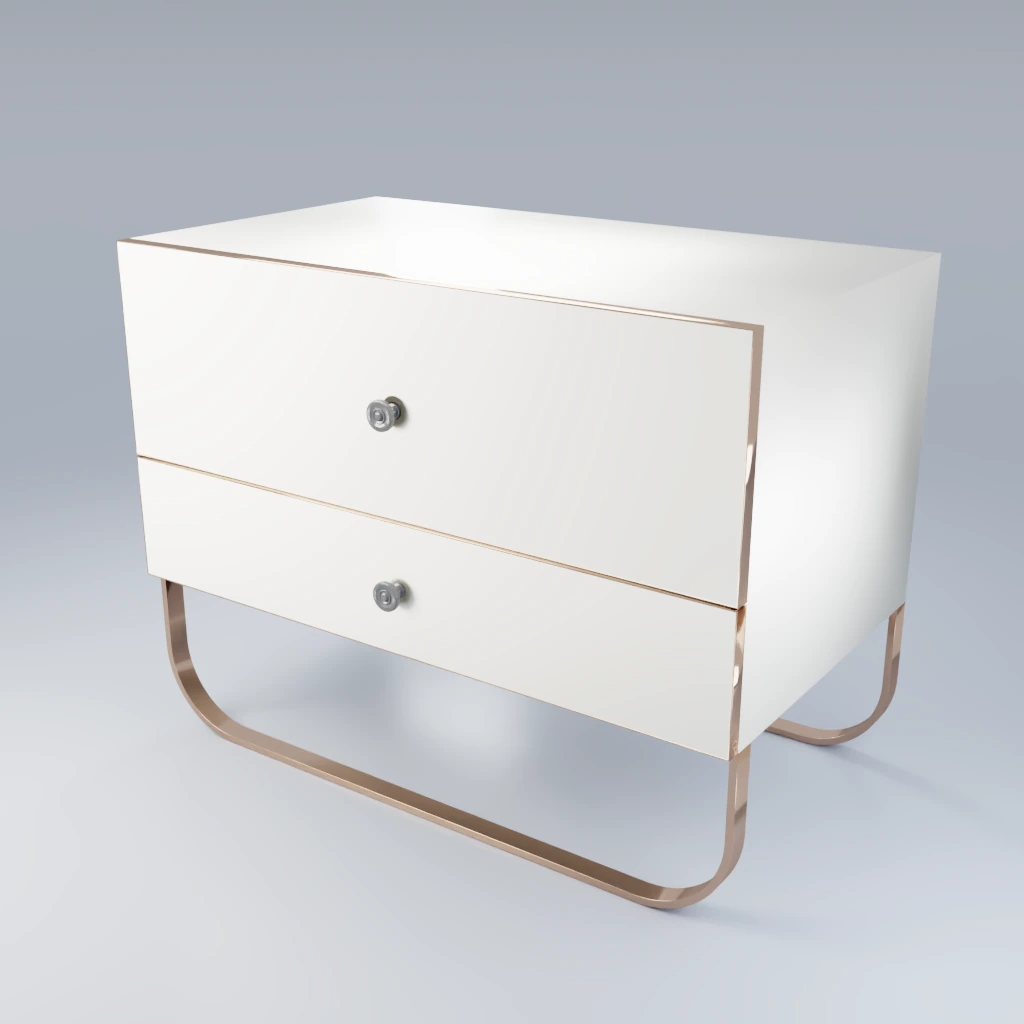
Its asset library contains 9,116 rigid objects across 1,071 categories and 2,507 articulated objects across 88 functional categories. γ-Sim also integrates 1,452 visual scenes and more than 10,000 high-resolution 4K indoor images generated with Qwen-Image to broaden scene and illumination coverage. Hunyuan-World 3DGS scenes and Hunyuan3D assets are additionally used for sim-to-real task synthesis.
Constraint-aware Cartesian trajectories, collision-aware GPU planning, and lower-velocity contact establishment are specialized for sustained articulated interactions such as doors, drawers, knobs, and appliance controls. An asynchronous plan-and-execute design scales collection across parallel environments.
γ-Sim builds executable task instances from a broad library of rigid and articulated objects, robot embodiments, and generated assets for sim-to-real task synthesis.
Representative robot platforms and configurable embodiment setups supported by γ-Sim.
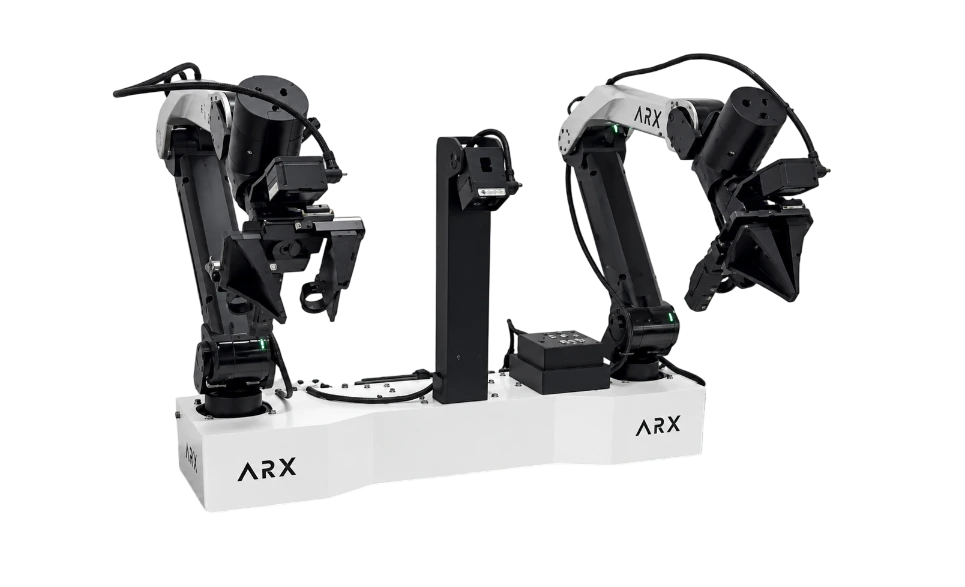
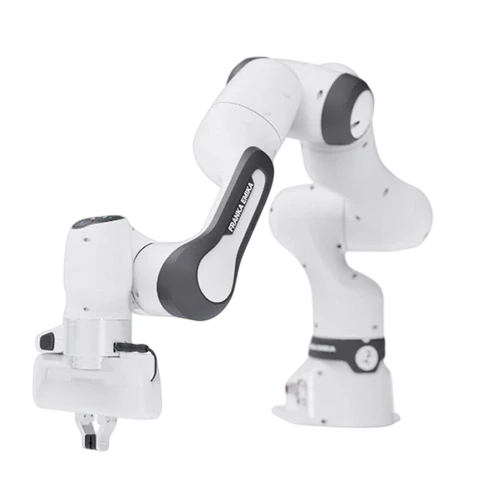
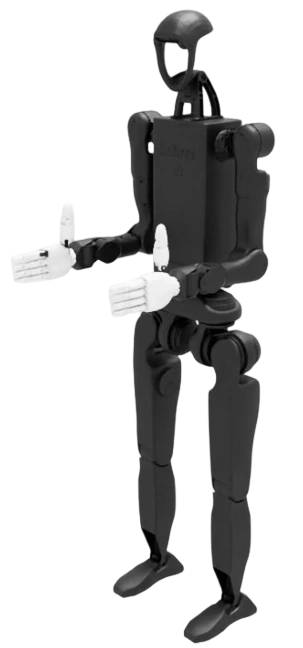
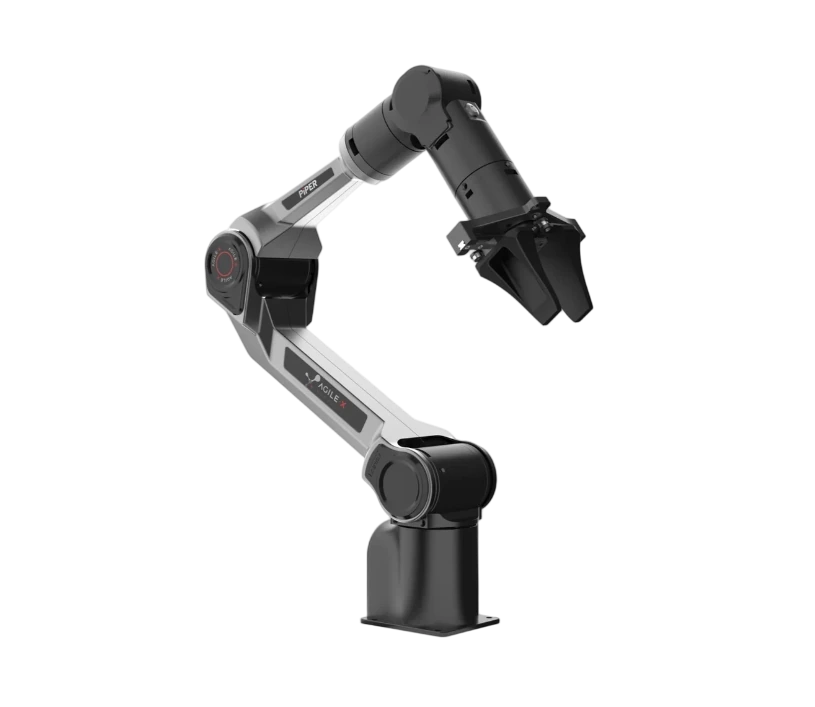
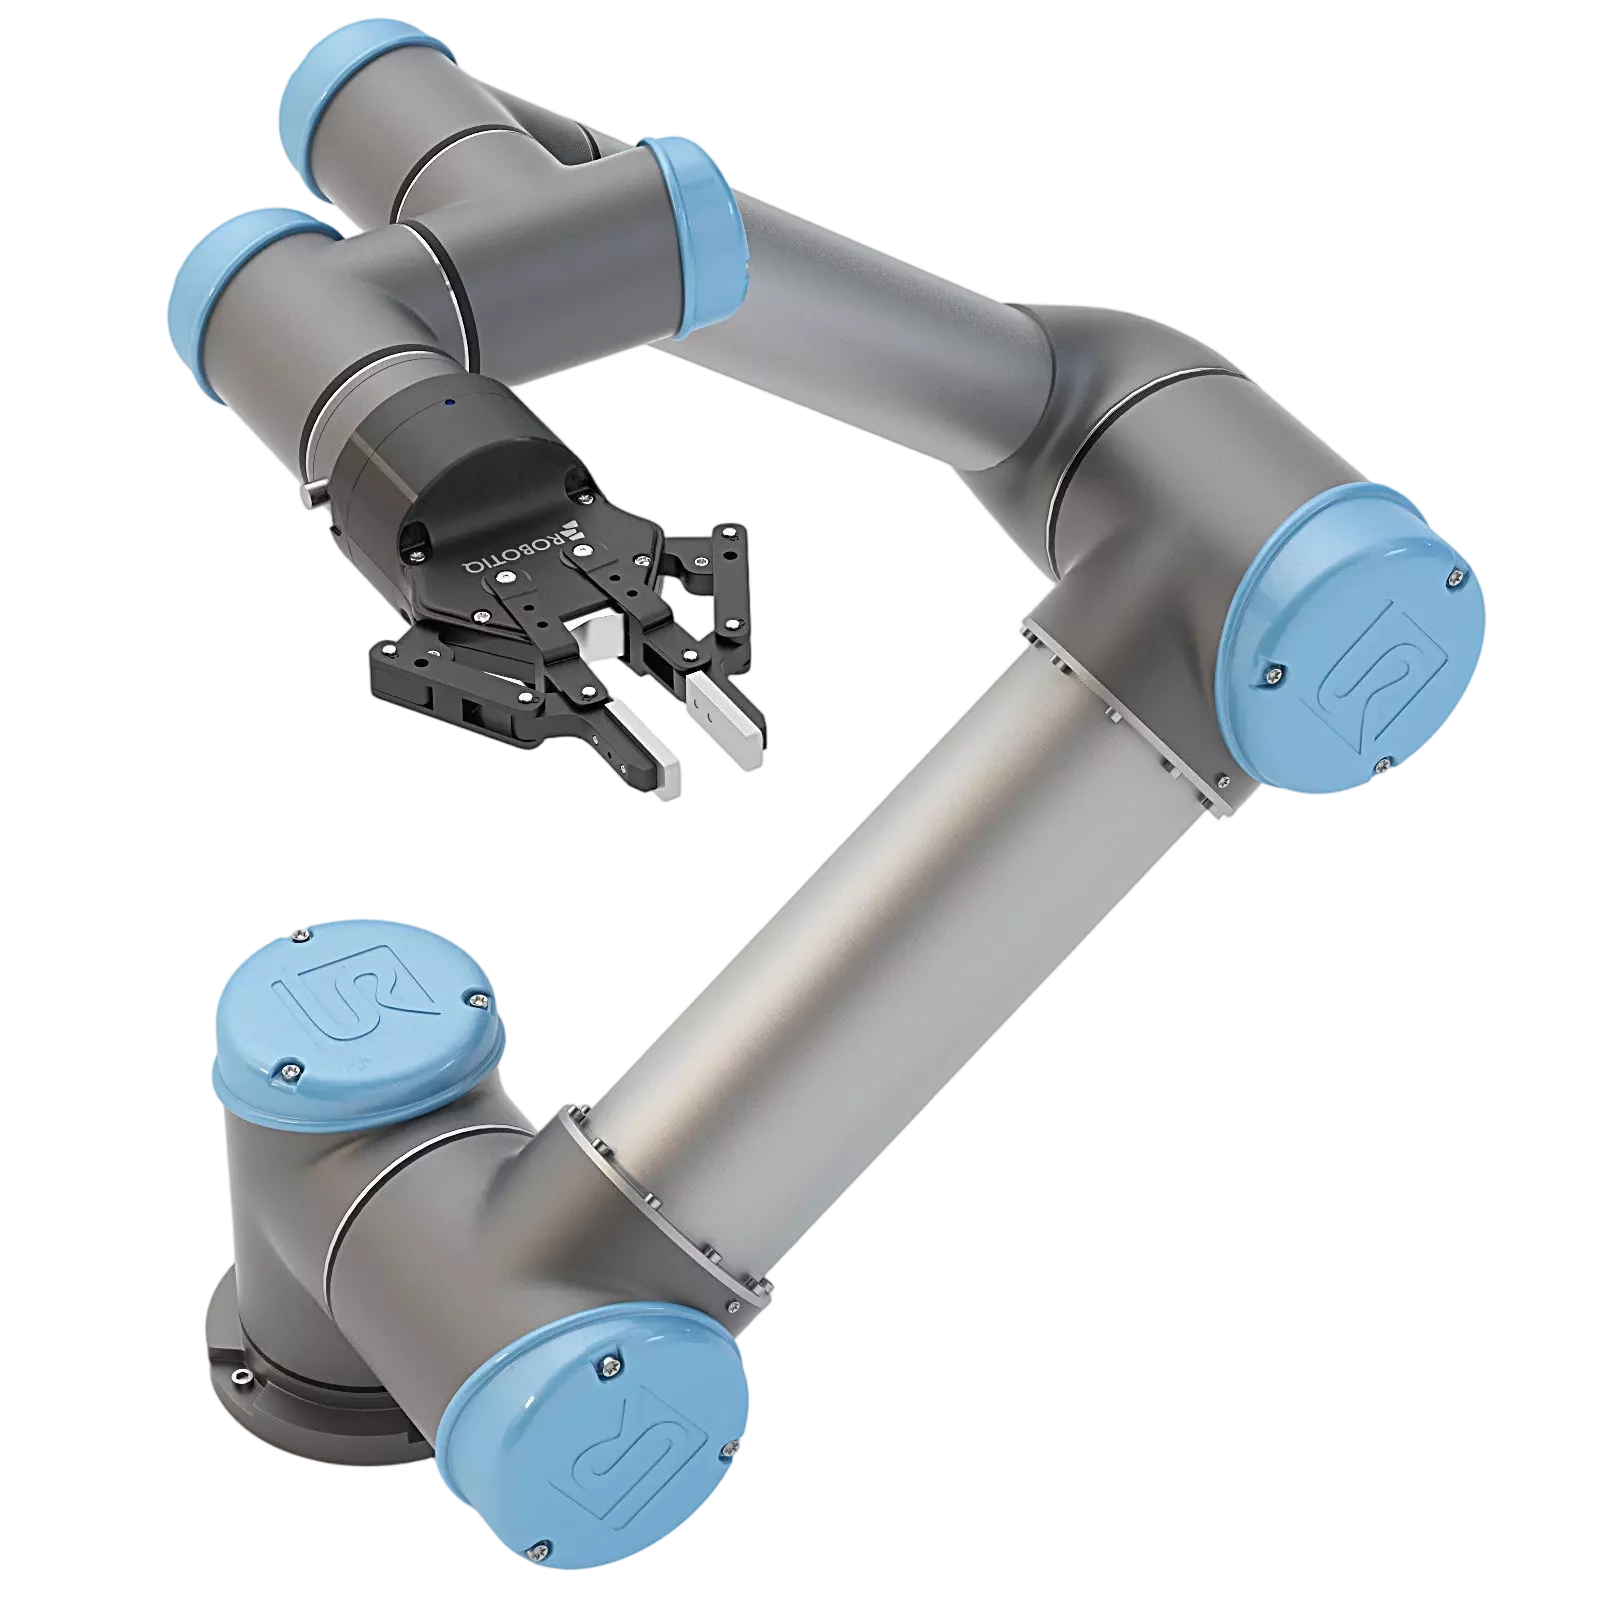
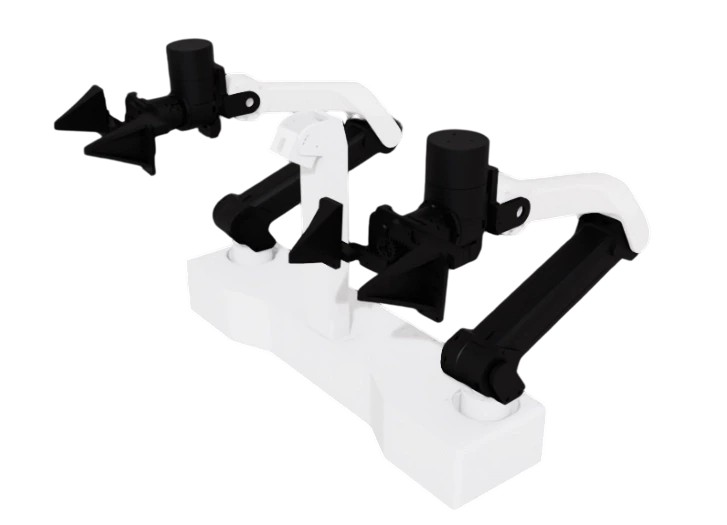
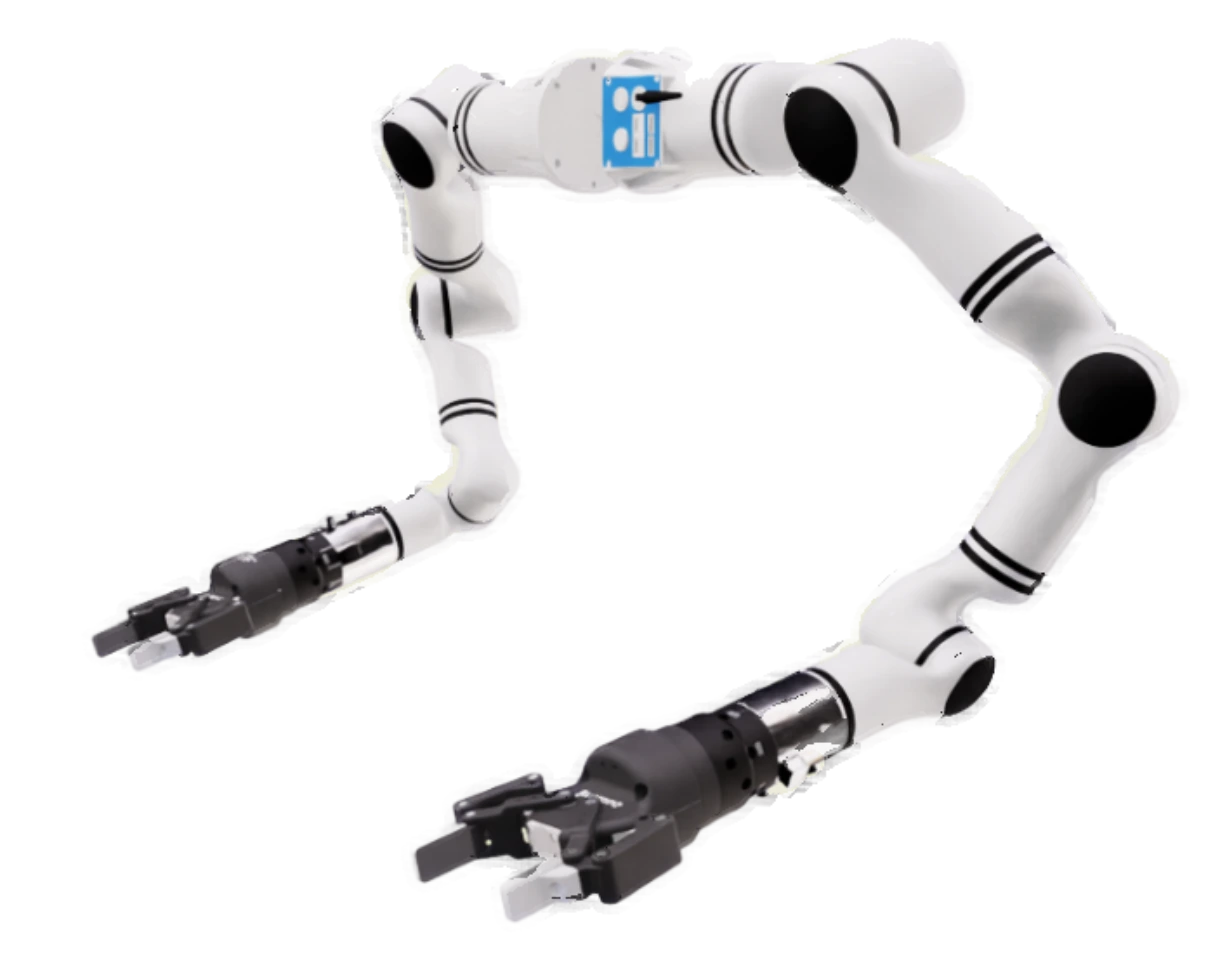
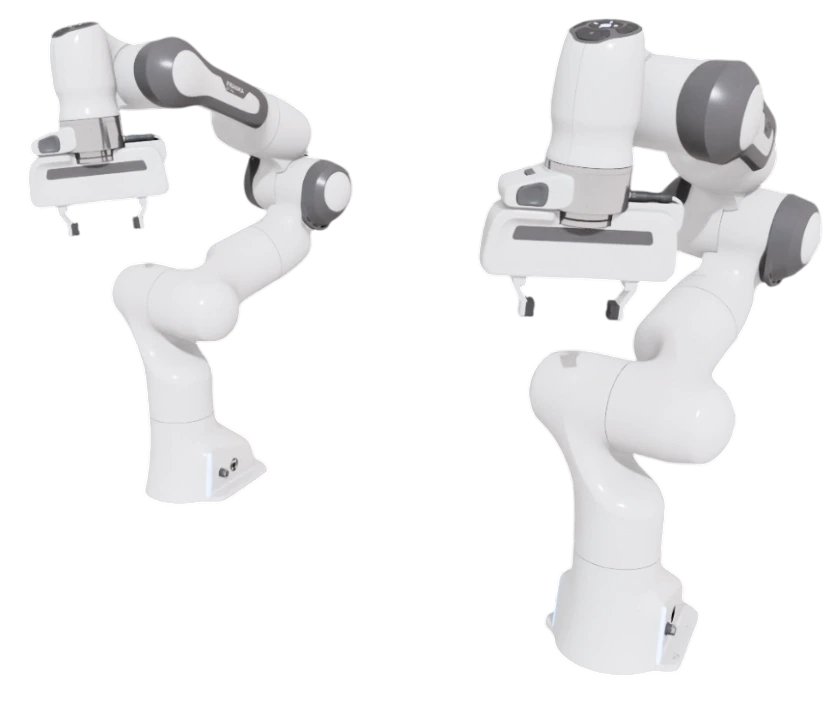
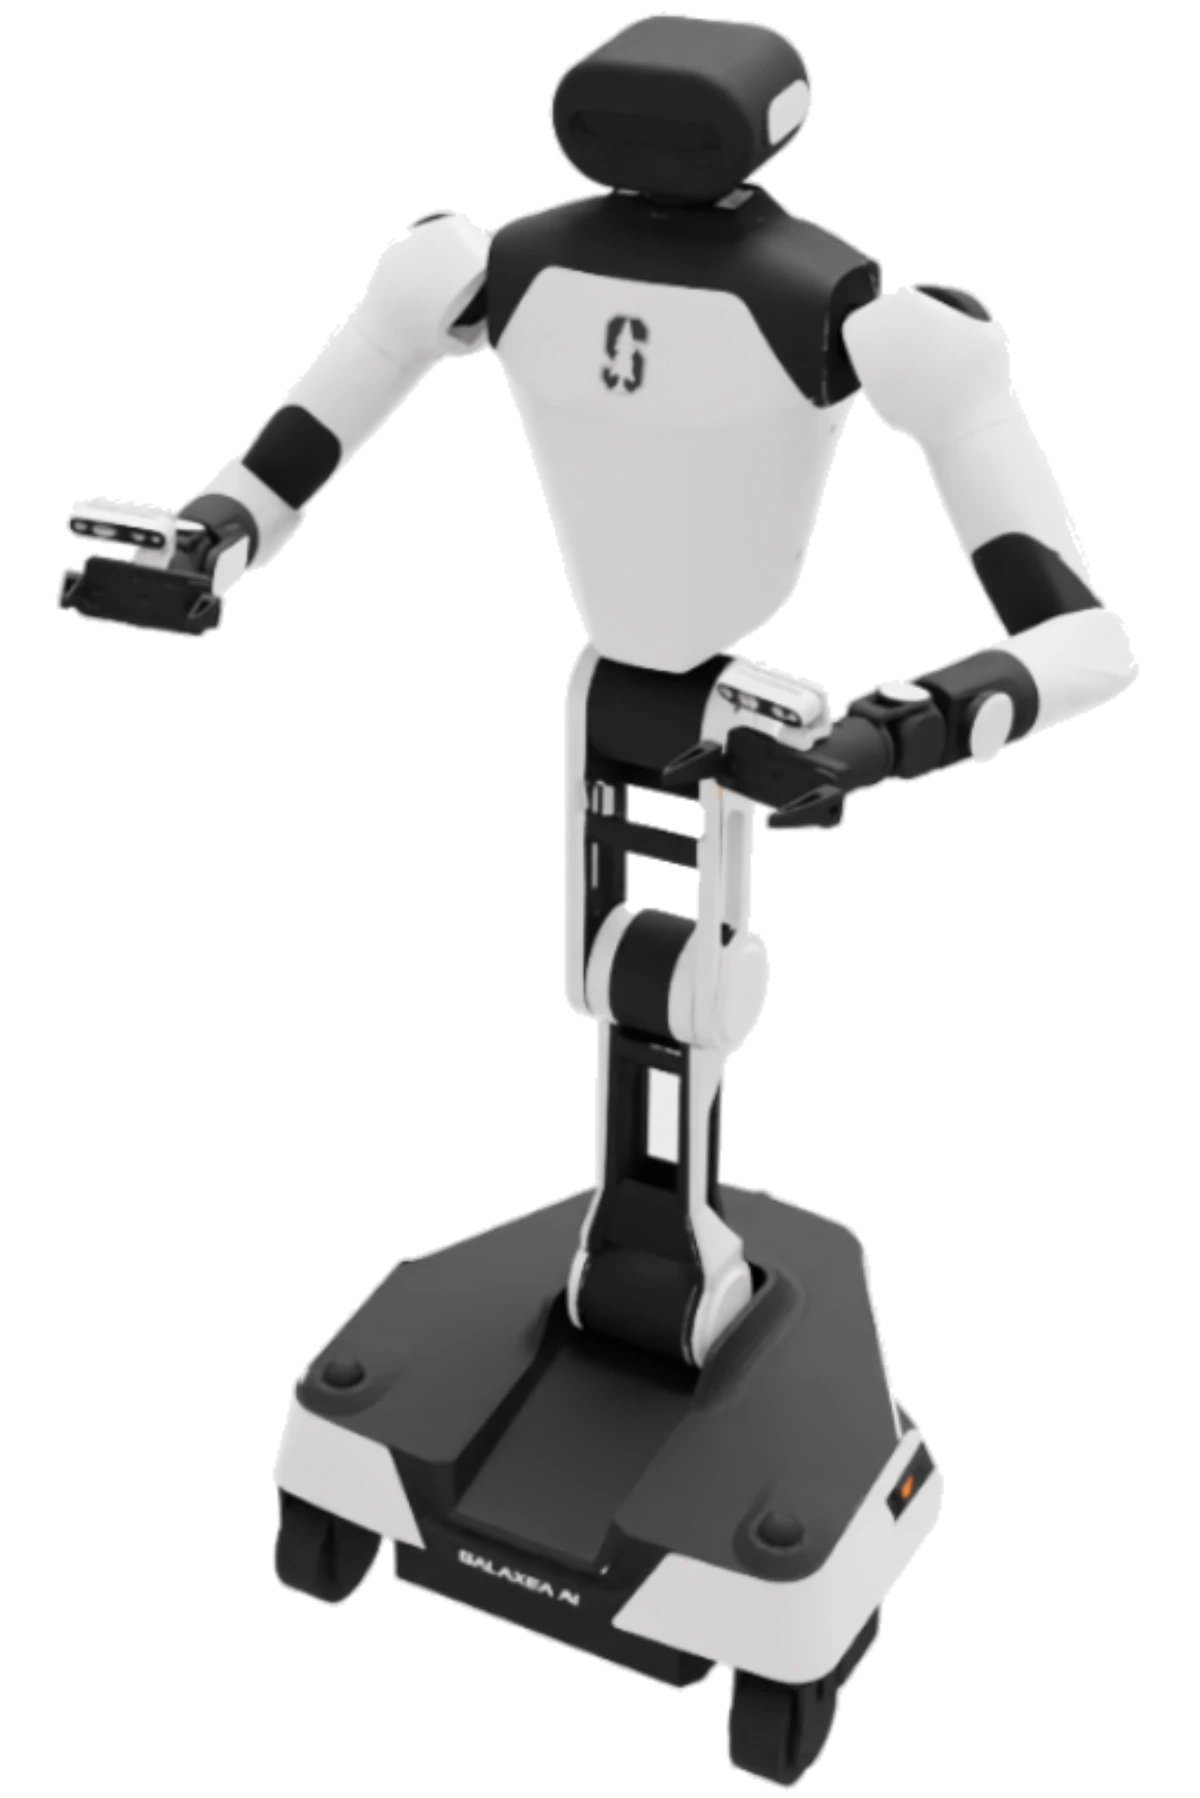
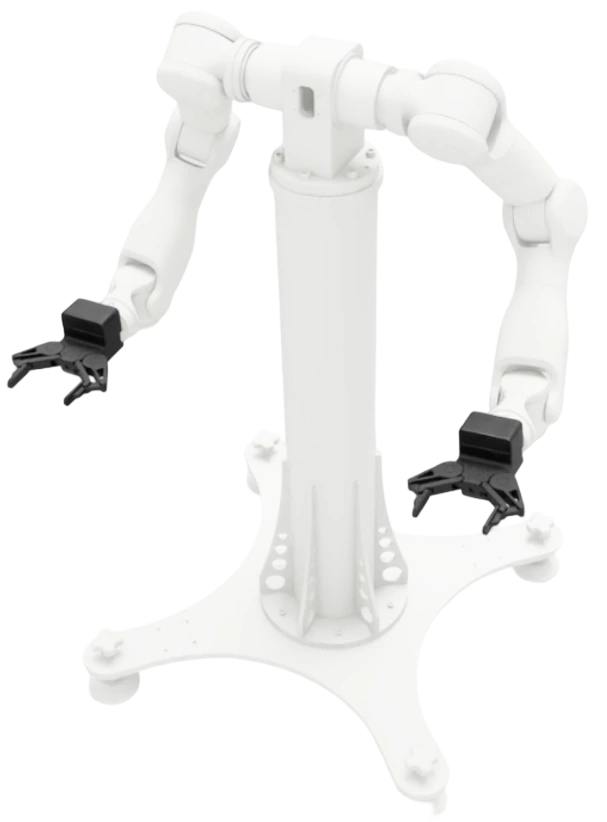
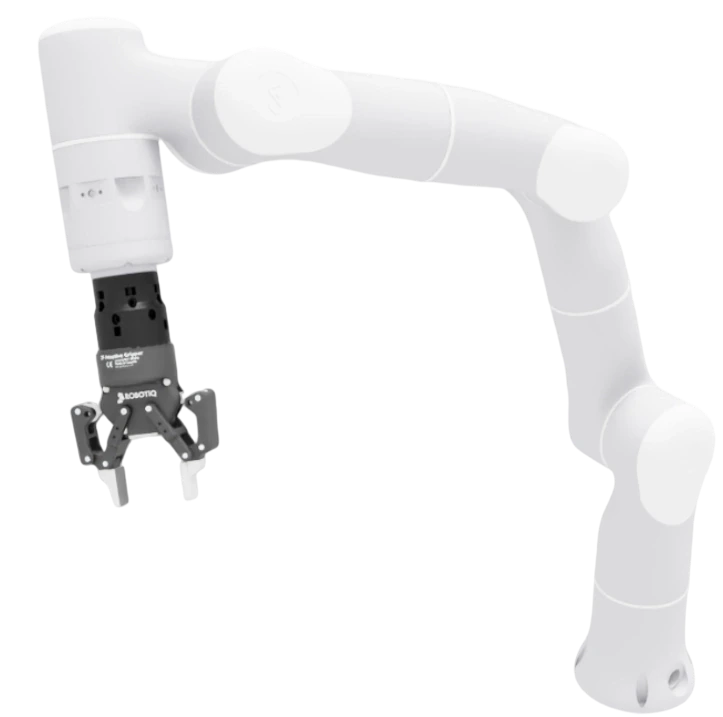
γ-Sim builds task instances from a broad library of rigid objects, articulated objects, robot embodiments, and generated assets for sim-to-real task synthesis.
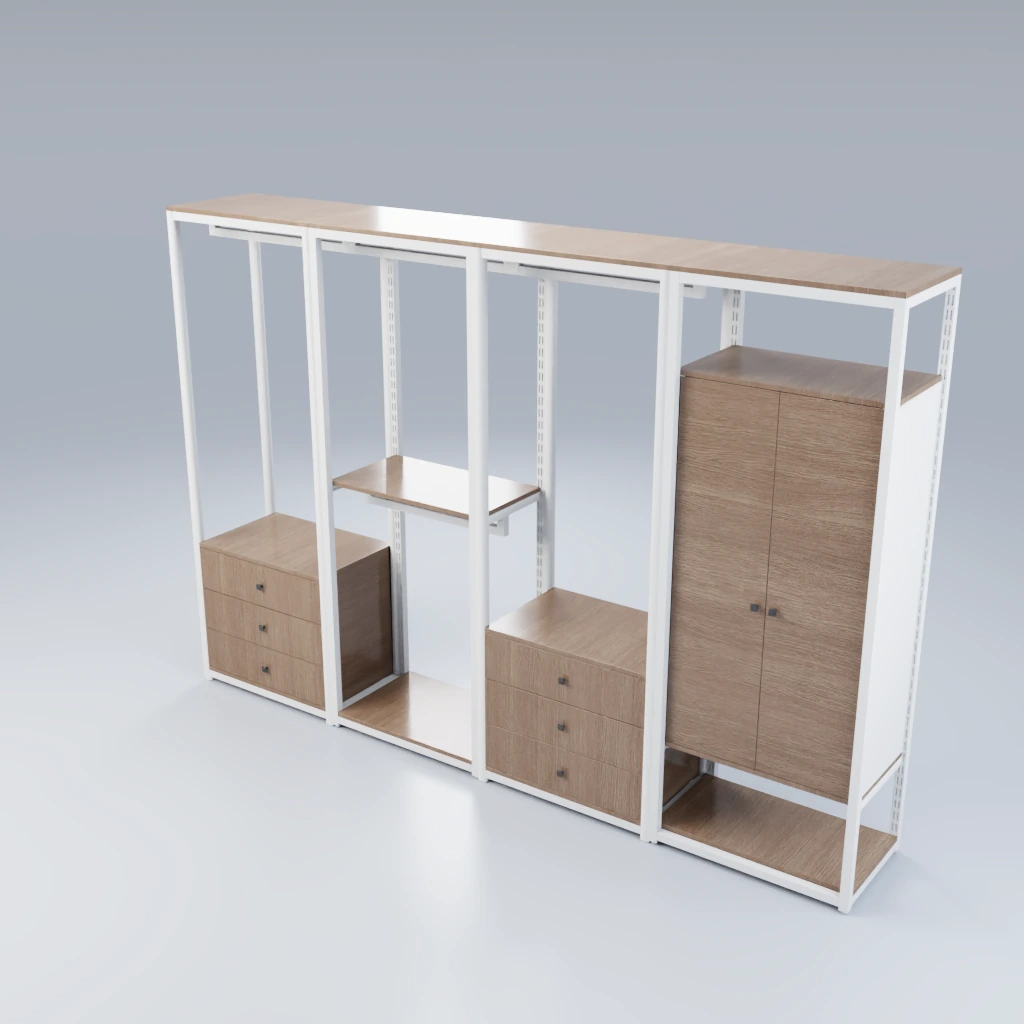
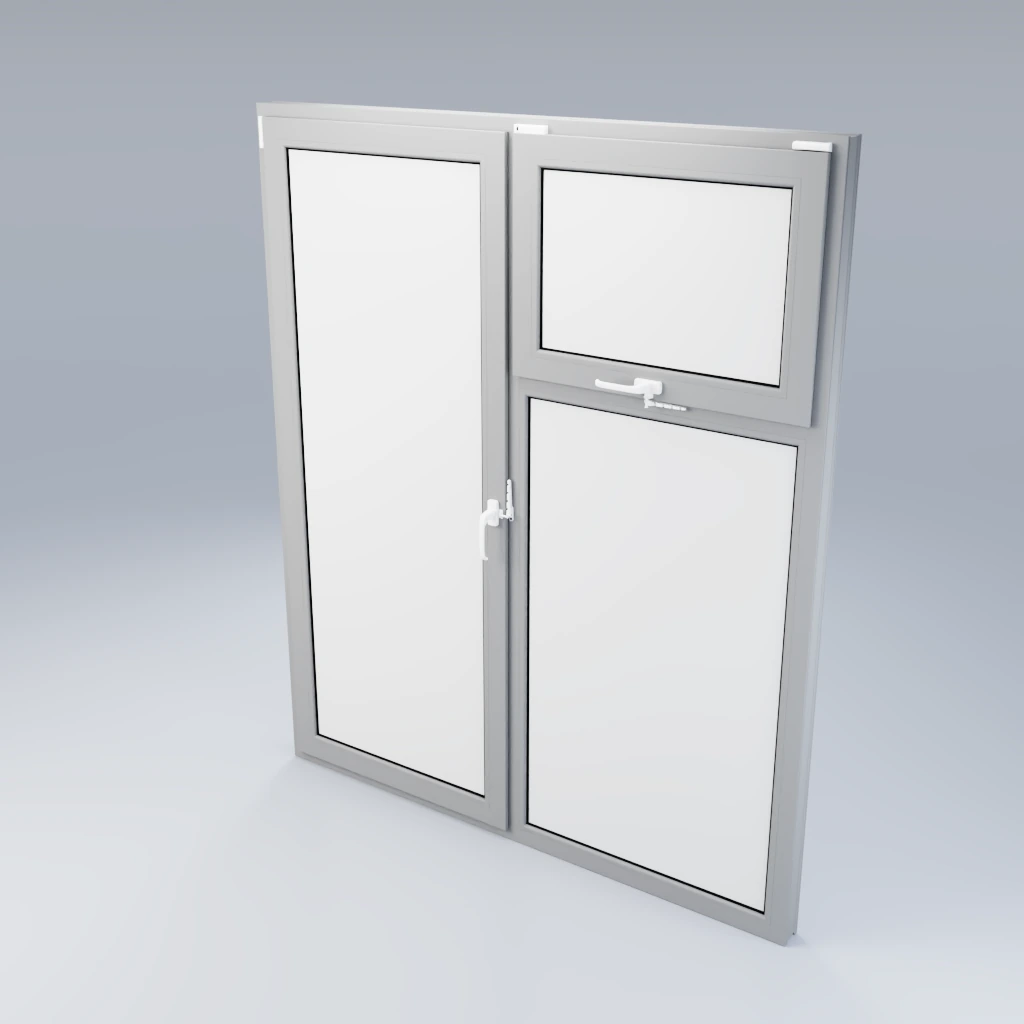
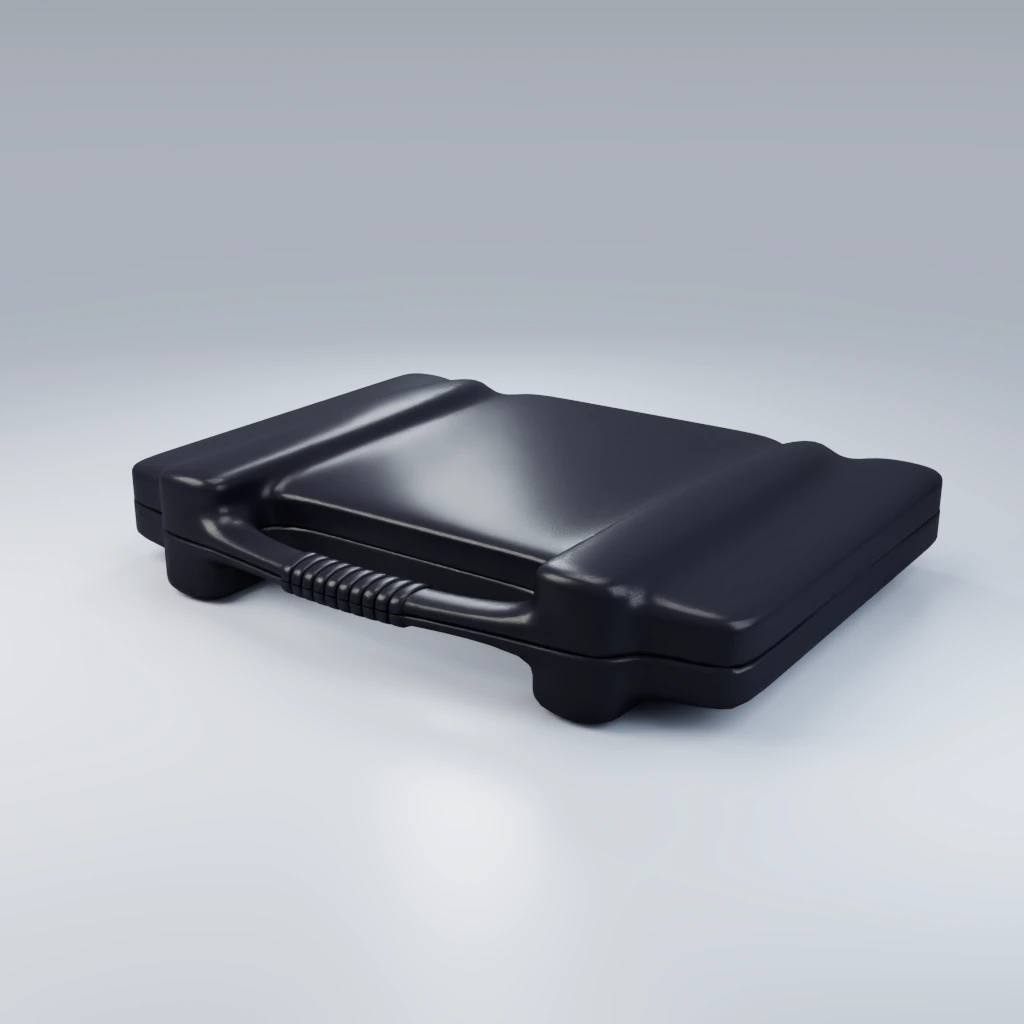
γ-Sim integrates 1,452 visual scenes and more than 10,000 high-resolution 4K indoor images, spanning bathrooms, bedrooms, kitchens, and living rooms.
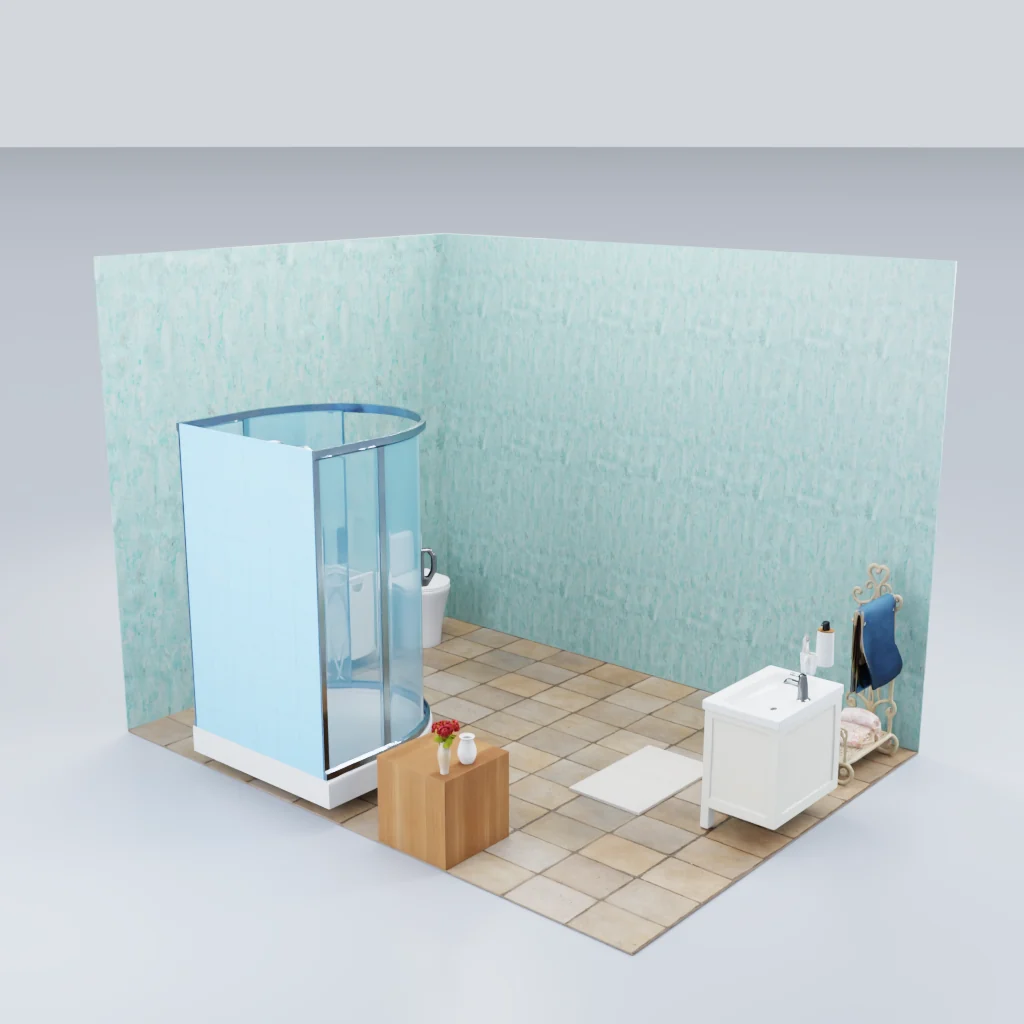
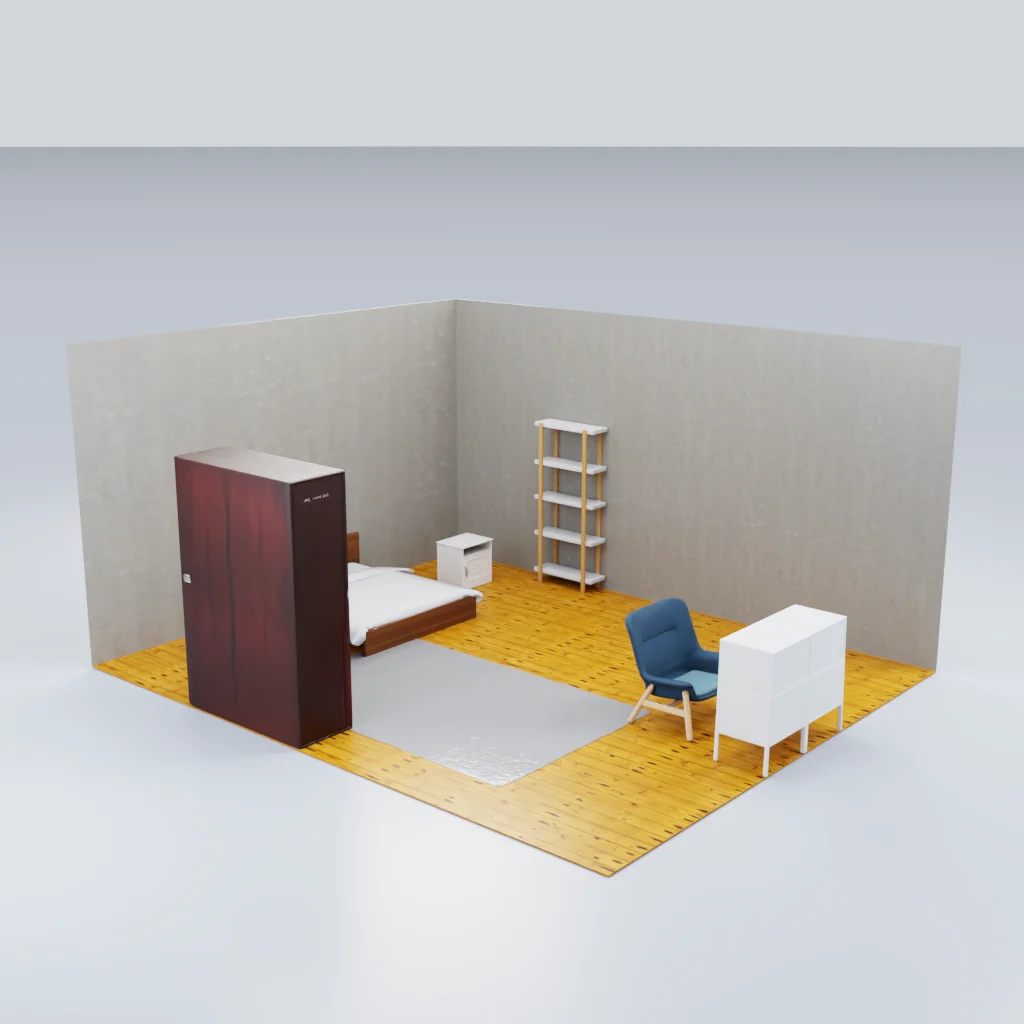
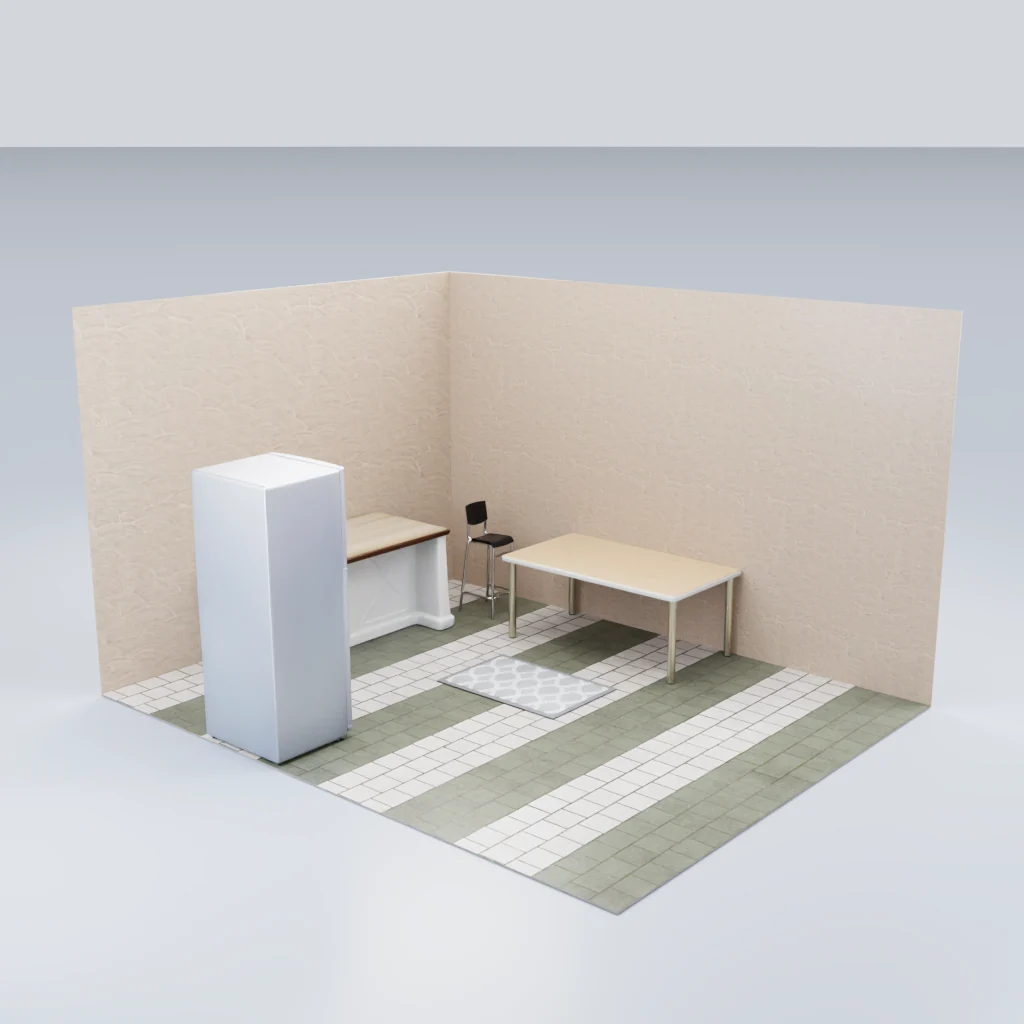
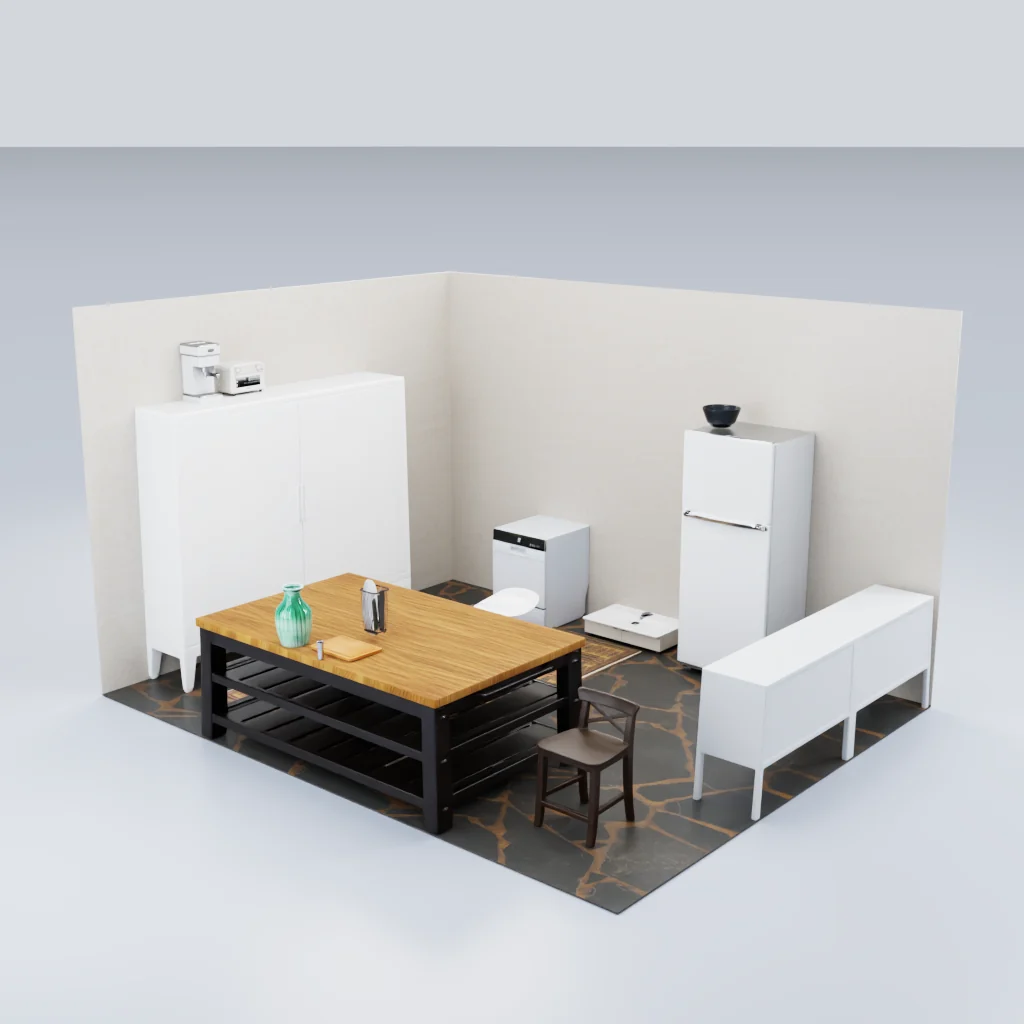
Rigid and articulated assets are annotated with geometry, category, and interaction metadata so they can be instantiated consistently across simulation tasks.
Rigid assets are organized by category and visual variants, with stable geometry and appearance metadata for placement, material randomization, and scene composition.
Articulated assets expose movable parts and joint semantics, including links, axes, limits, and interaction regions for constraint-aware motion generation.
Domain randomization increases demonstration diversity while preserving articulated-part semantics through spatial, physical, and visual variation:
03 Data Synthesis
γ-Art connects task authoring to large-scale demonstration production. A task-generation agent first grounds natural language in executable simulation configurations; distributed workers then decouple trajectory rollout, multi-view rendering, and dataset conversion so failed trajectories do not consume the rendering budget. At scale, each 8-GPU server produces approximately 144 hours of data per day.
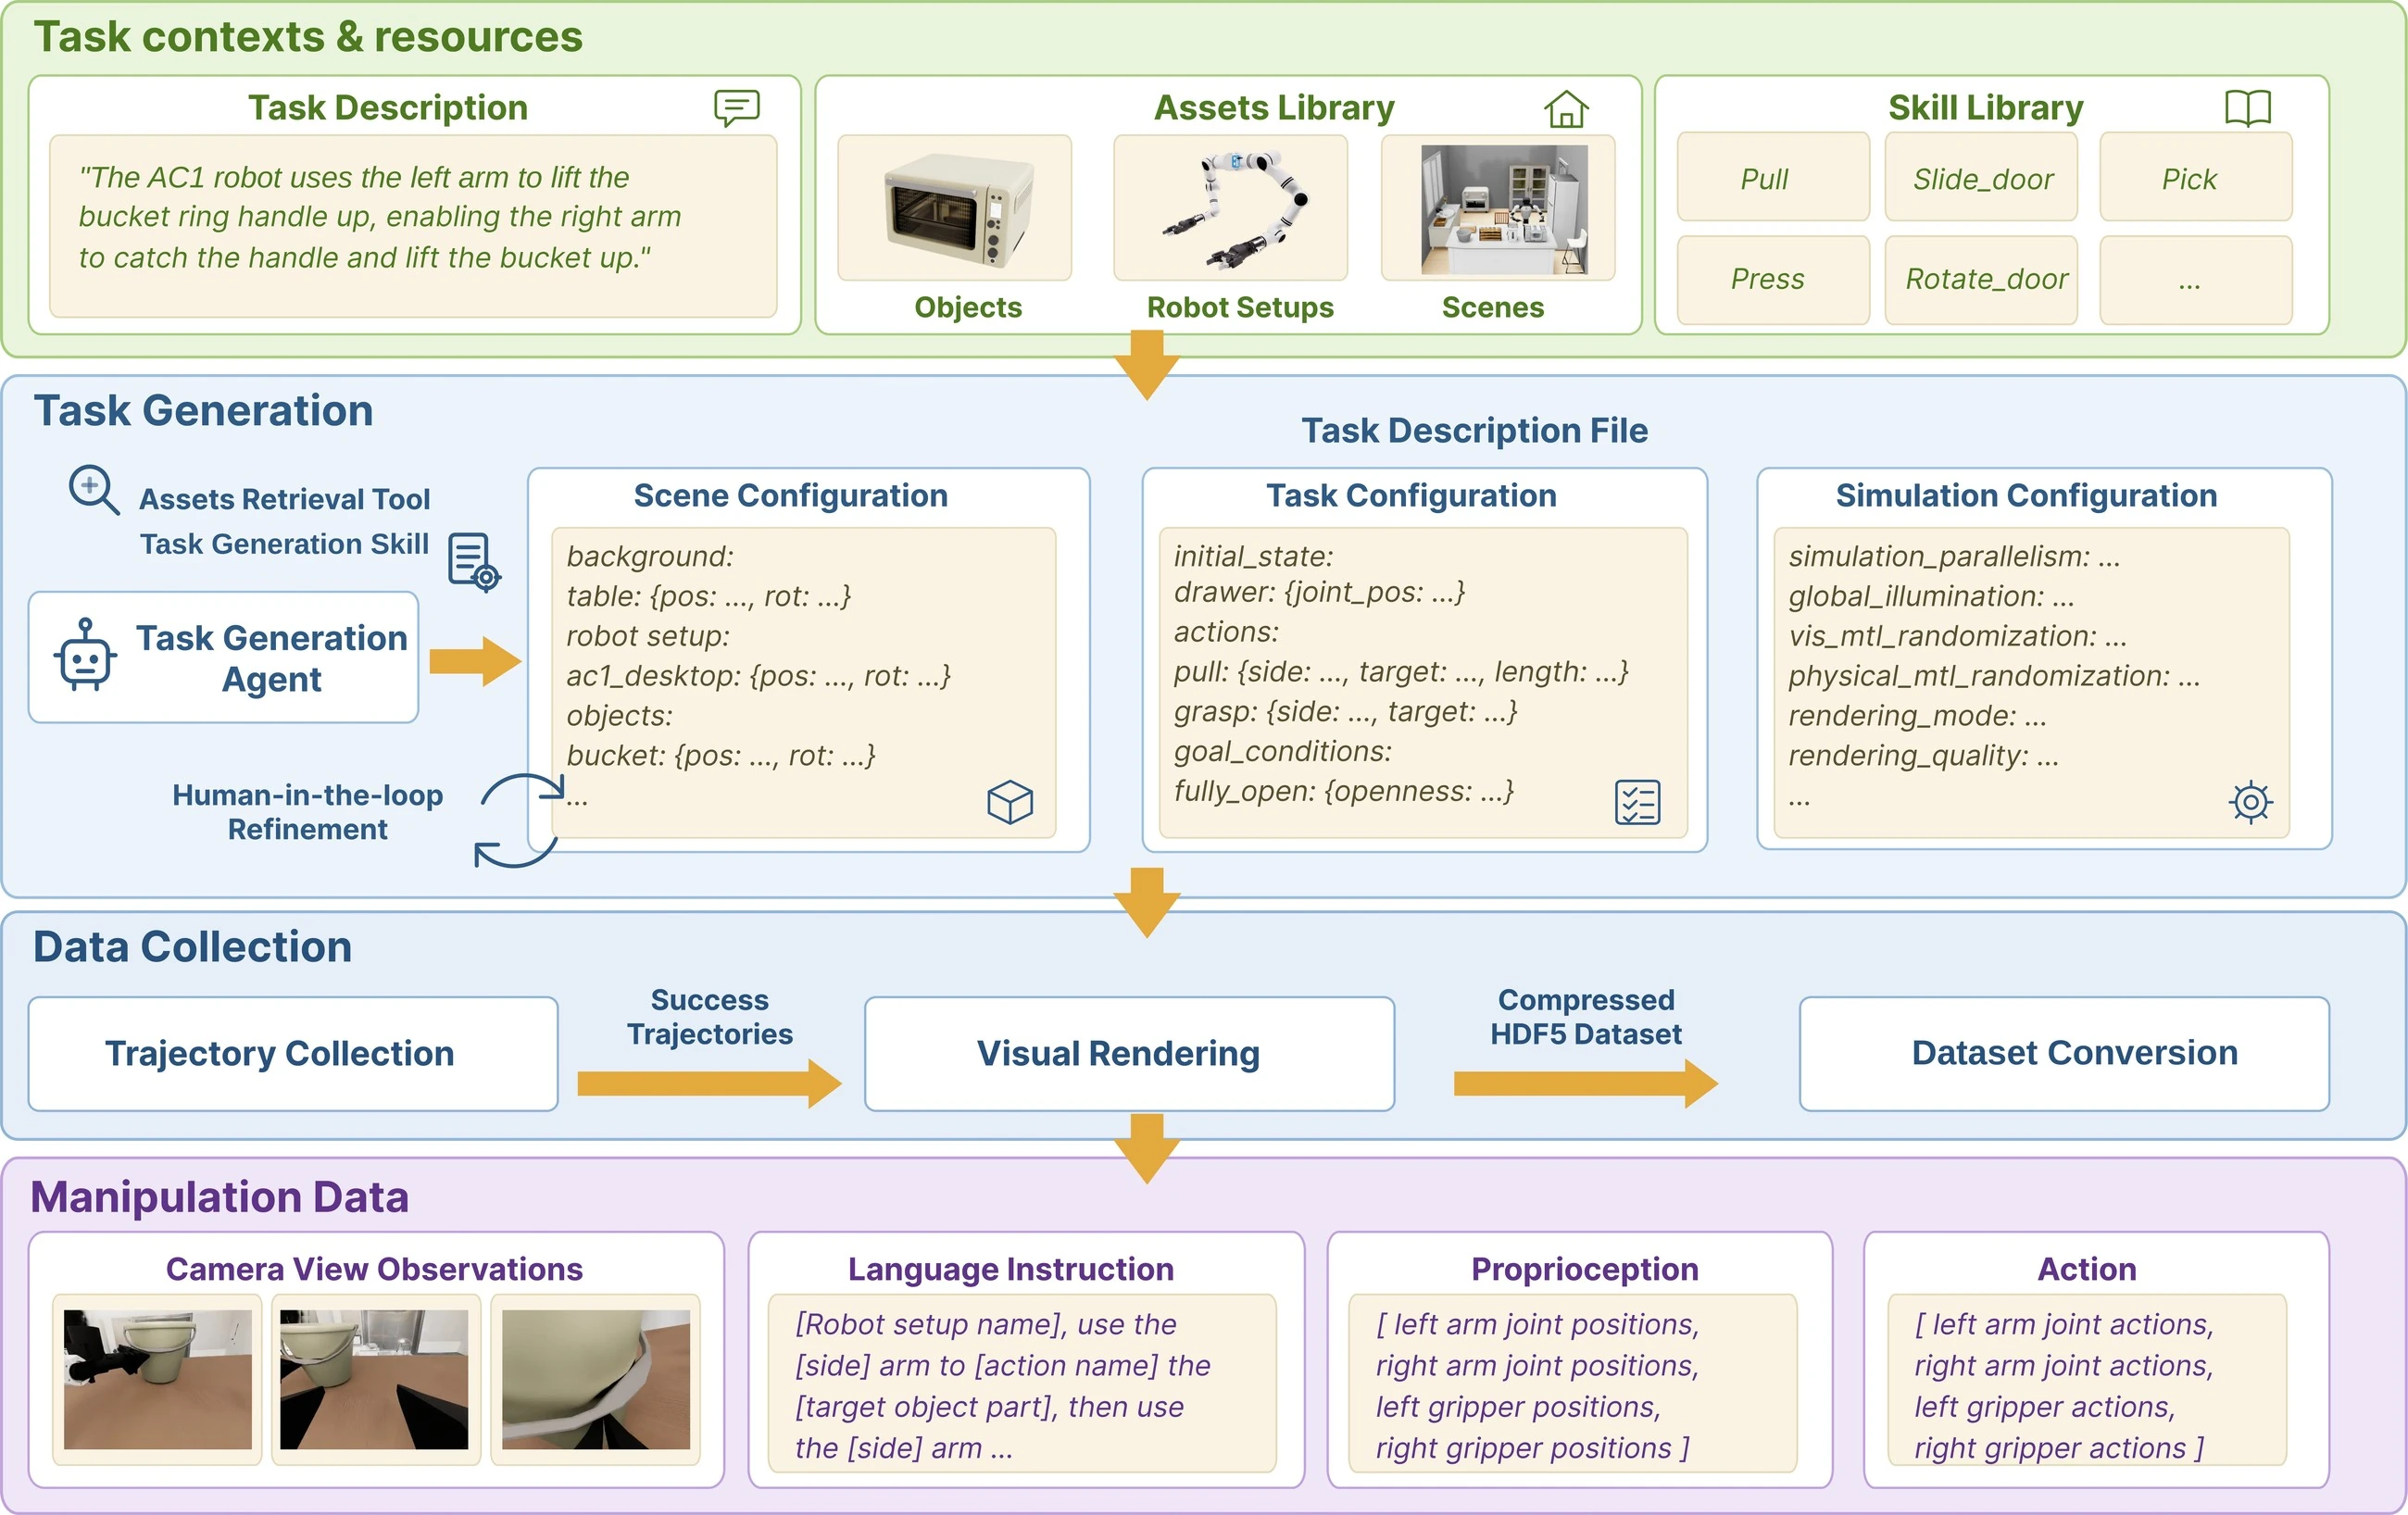
A task-generation agent converts a natural-language manipulation request into a grounded, executable simulation configuration. The agent reasons over the asset catalog, part-level manipulation annotations, and examples of valid task files rather than creating simulator calls directly from unconstrained text.
Large-scale synthesis separates CPU-bound planning from GPU-intensive rendering. A scheduler coordinates three workload types across shared GPU and CPU resources, while quality checks remove unstable or unsuccessful rollouts before they reach the rendering stage.
04 Dataset
γ-Art-Data is a large-scale synthetic dataset produced by γ-Sim for articulated-object manipulation. It contains 1,004,584 trajectories, approximately 500 million frames, and more than 4,600 hours of manipulation data across five robot setups.
It covers 44 task types and 23 reusable skills, with 2,507 articulated objects spanning 23 functional categories in the collected trajectories and 88 categories in the full asset library. Examples include cabinets, drawers, windows, refrigerators, ovens, dishwashers, dispensers, and microwave controls. Each demonstration contains multi-view observations, proprioceptive states, language instructions, and action trajectories in a standardized LeRobot v3.0 format.
The dataset includes atomic, composite, and long-horizon tasks (69.4%, 20.9%, and 9.7%), plus variation in object placement, camera parameters, robot initial configuration, physical properties, materials, and illumination. These controlled variations target the visual, geometric, and contact-related sources of the sim-to-real gap.


05 Results
The model borrows the PRTS architecture: a Qwen3-VL-4B backbone with a DiT-based action expert trained with flow matching. For controlled comparisons, the CRL objective is removed. γ-Art-VLA uses γ-Art-Data for first-stage behavior-cloning pretraining, then is post-trained on the downstream benchmark; γ-Art-VLA(w/o S1) skips first-stage pretraining. On standard post-training settings, γ-Art-VLA reaches 96.8% average success on LIBERO and 28.8% on RoboCasa365.
On LIBERO, γ-Art-VLA exceeds γ-Art-VLA(w/o S1) by 2.1 points (96.8% vs. 94.7%), surpasses π0 (94.2%) and Qwen3-VL-π (94.7%), and approaches π0.5 (96.9%) and γ-Art-VLA(Real) (97.8%), which uses real-world pretraining. On RoboCasa365, γ-Art-VLA outperforms the strongest listed baseline, GR00T N1.5 (23.9%), despite using synthetic pretraining only. γ-Art-VLA also exceeds π0.5 by 11.9 points on RoboCasa365 and demonstrates an earlier performance advantage during post-training, while γ-Art-VLA(w/o S1) reaches 89.9% at the same point.
Average success rate across the LIBERO benchmark suites (%).
| Method | Average |
|---|---|
| π0 | 94.2 |
| Qwen3-VL-π | 94.7 |
| π0.5 | 96.9 |
| γ-Art-VLA (Real) | 97.8 |
| γ-Art-VLA (w/o S1) | 94.7 |
| γ-Art-VLA | 96.8 |
Success rate by task split (%); bold values indicate the best result in each column.
| Method | Atomic Seen | Composite Seen | Composite Unseen | Average |
|---|---|---|---|---|
| π0 | 34.6 | 6.1 | 1.1 | 14.8 |
| π0.5 | 39.6 | 7.1 | 1.2 | 16.9 |
| GR00T N1.6 | 51.1 | 9.4 | 1.7 | 21.9 |
| GR00T N1.5 | 50.7 | 14.8 | 2.7 | 23.9 |
| γ-Art-VLA (w/o S1) | 43.3 | 9.4 | 4.4 | 20.0 |
| γ-Art-VLA | 52.8 | 23.1 | 7.5 | 28.8 |
A key result is zero-shot sim-to-real transfer: models are post-trained with synthetic task demonstrations only, without task-specific real-world demonstrations, and then evaluated on physical robots. The evaluation covers 12 articulated-object tasks across a dual-arm RealMan RM75, R1Pro, and ARX AC-1. Each platform uses three RGB cameras, including one center camera and one wrist camera on each arm. We synthesize 500 demonstrations per task in approximately two hours and measure success over 15 independent trials.
γ-Art-VLA achieves 76.7% overall success, compared with 50.0% for γ-Art-VLA(w/o S1), 59.4% for π0.5, and 69.4% for γ-Art-VLA(Real). It matches or outperforms γ-Art-VLA(w/o S1) on every matched task; the largest gains are 46.7 points on RM75 bucket-handle lifting and AC-1 drawer pulling. Performance also scales positively as synthetic task demonstrations increase from 1 to 500 episodes.

Real-world evaluation across three robot platforms and twelve tasks; success rates are measured over 15 trials.
Increasing the task-specific synthetic dataset from 1 to 500 episodes produces a positive success-rate trend. At 500 episodes, γ-Art-VLA exceeds 80% on each of the five scaling tasks shown below; constrained actions such as drawer pulling and knob rotation continue to benefit from additional demonstrations.


06 Gallery
@article{smart2026,
  title={SMART: Zero-Shot Sim-to-Real Articulated Object Manipulation via Large-Scale Synthetic Pretraining},
  author={Ao, Jicong and Jiang, Shuhan and Zhong, Yuling and Liu, Yanwen and Gao, Yuhan and Zhao, Jiangyuan and Zhang, Yang and Zhu, Shiqiang and Bai, Chenjia and Li, Xuelong},
  year={2026},
  url={https://arxiv.org/abs/2610.07652}
}